H3C shifts its focus from merely increasing GPU count to enhancing Token efficiency, redefining AI infrastructure and operational strategies.
Rethinking AI Infrastructure Efficiency
If the recent trend in AI infrastructure revolved around increasing compute power, the entry of Agentic AI is compelling the industry to address a more pressing question: How can existing compute resources be used more efficiently?
During the 2026 Apsara Conference, H3C framed this challenge through the lens of Tokens. With AI agents increasingly relying on foundation models, demand is growing for services that can handle trillions of Tokens, posing new operational requirements.
The Reality of GPU Performance
The assumption that adding more GPUs equates to superior performance is simplistic. Factors such as idle compute resources, network congestion, and the technical complexities involved with large-scale clusters can undermine the effectiveness of additional GPUs.
H3C’s latest product range illustrated this pivot towards efficiency rather than sheer quantity. Their offerings cover a spectrum from computing power to networking and storage, emphasizing a cohesive system optimization approach rather than just piling on hardware.
AI Clusters: A Systematic Approach
Zhu Shiyin, general manager of H3C’s Advanced Technology Research Department, discussed the concept of AI clusters as integrated systems requiring adept hardware-software coordination. When clusters expand from hundreds to thousands, and even tens of thousands, of GPUs, it’s crucial to manage not only the GPUs but also factors like communication between chips, data transfer dynamics, job scheduling, and power management.
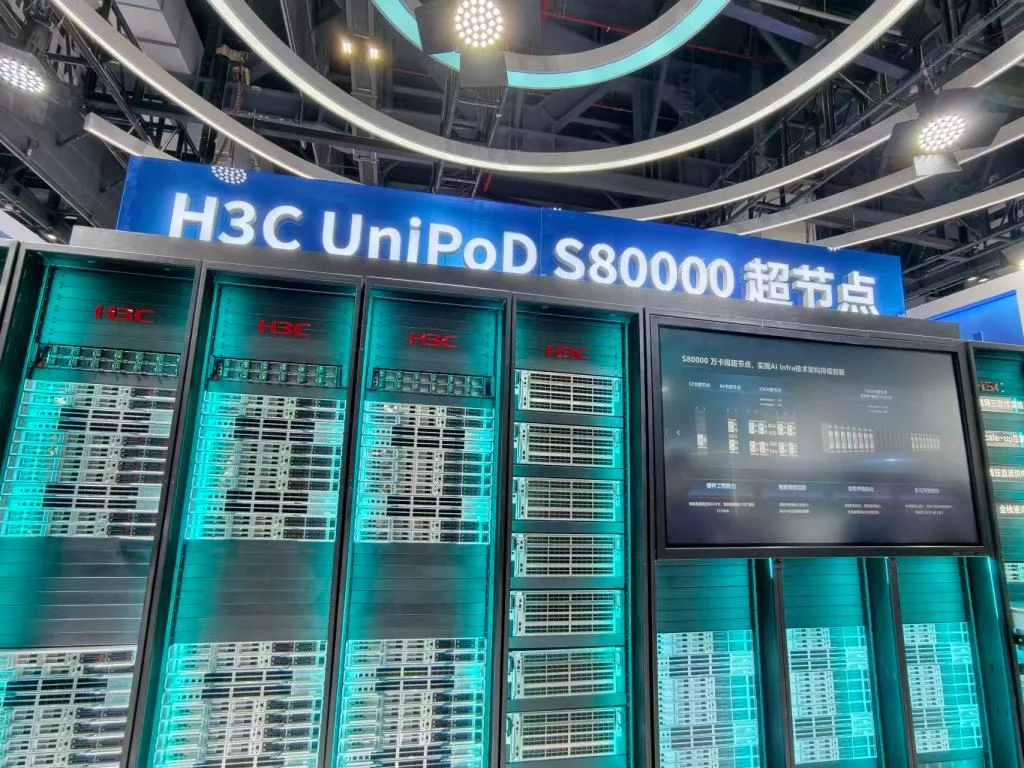
The UniPoD S80000 Series SuperPod showcased at the conference embodies this philosophy. It accommodates configurations with 32 to 1,024 GPUs, capable of scaling further to 16,384. This adaptability allows it to integrate various computing resources, including CPUs, GPUs, NPUs, and DPUs, while supporting widely adopted frameworks. H3C is pushing the narrative that competition is shifting toward the actual amount of useful Tokens—essentially the measurable output—each GPU can provide, rather than just the volume of hardware present.
Network Speed: The Next Bottleneck
As GPUs evolve in efficiency, the network's ability to keep pace becomes critical. Zhu pointed out that improved GPU performance leads to an increased volume of data transferred between them; if the network lags, GPUs end up idling.
To address this, H3C introduced several interconnect scenarios at the conference: Scale-Up, Scale-Out, and Scale-Across. They highlighted the S9828-128EO, a 102.4T NPO silicon-photonics intelligent switch engineered with co-packaged optics which significantly reduces latency. Additionally, the S9828-64FP switch employs advanced technologies to optimize power consumption in dense environments, further enhancing the viability of large cluster deployments.
Data Management: An Overlooked Factor
The efficient operation of GPU resources heavily relies on data accessibility. Data movements are intrinsic to stages like training and inference, adding strain on both storage and caching solutions. Recognizing this, H3C has branded high-performance storage as an integral part of the Token production ecosystem.
The UniStor X20000 series X20836 offers impressive stats with up to 200GB/s bandwidth and supports interoperability across various protocols. H3C claims that its high-performance engines can reduce waiting times for GPUs by 30% and accelerate inference processes dramatically, minimizing latency during Token generation.
Software: The Next Competitive Edge
Once hardware infrastructure is sufficiently advanced, the focus shifts toward software capabilities. Zhu emphasized that optimizing communication libraries, management frameworks, and scheduling tools can significantly diminish GPU idle time and reduce conflicts during operation. This harmony among components is essential; a failure in one area can lead to a cascading effect, hindering the overall Token output.
Future Directions: Efficiency Over Quantity
From H3C’s displays to workshops at the Apsara Conference, a consistent message emerged: it’s not just about how compute resources are used, but how effectively they can interoperate at scale. High-speed connectivity, intelligent clustering, and optimized storage solutions collaborate to ensure that AI capabilities are deployed efficiently and effectively.
The next competitive landscape in AI infrastructure isn’t simply about amassing GPUs; it’s about refining utilization. As model complexity escalates to trillions of parameters, the measurement of success may hinge on factors like compute efficiency, Token throughput, responsiveness, power usage, and production costs associated with each Token.
The larger implication here is clear: as the AI industry transitions into a phase characterized by large-scale production, compute challenges don’t isolate to just hardware specifications—they are expanding into overall system performance, driving a fundamental reevaluation of how infrastructure is designed and utilized.
Discussion
Sign in to join the discussion.